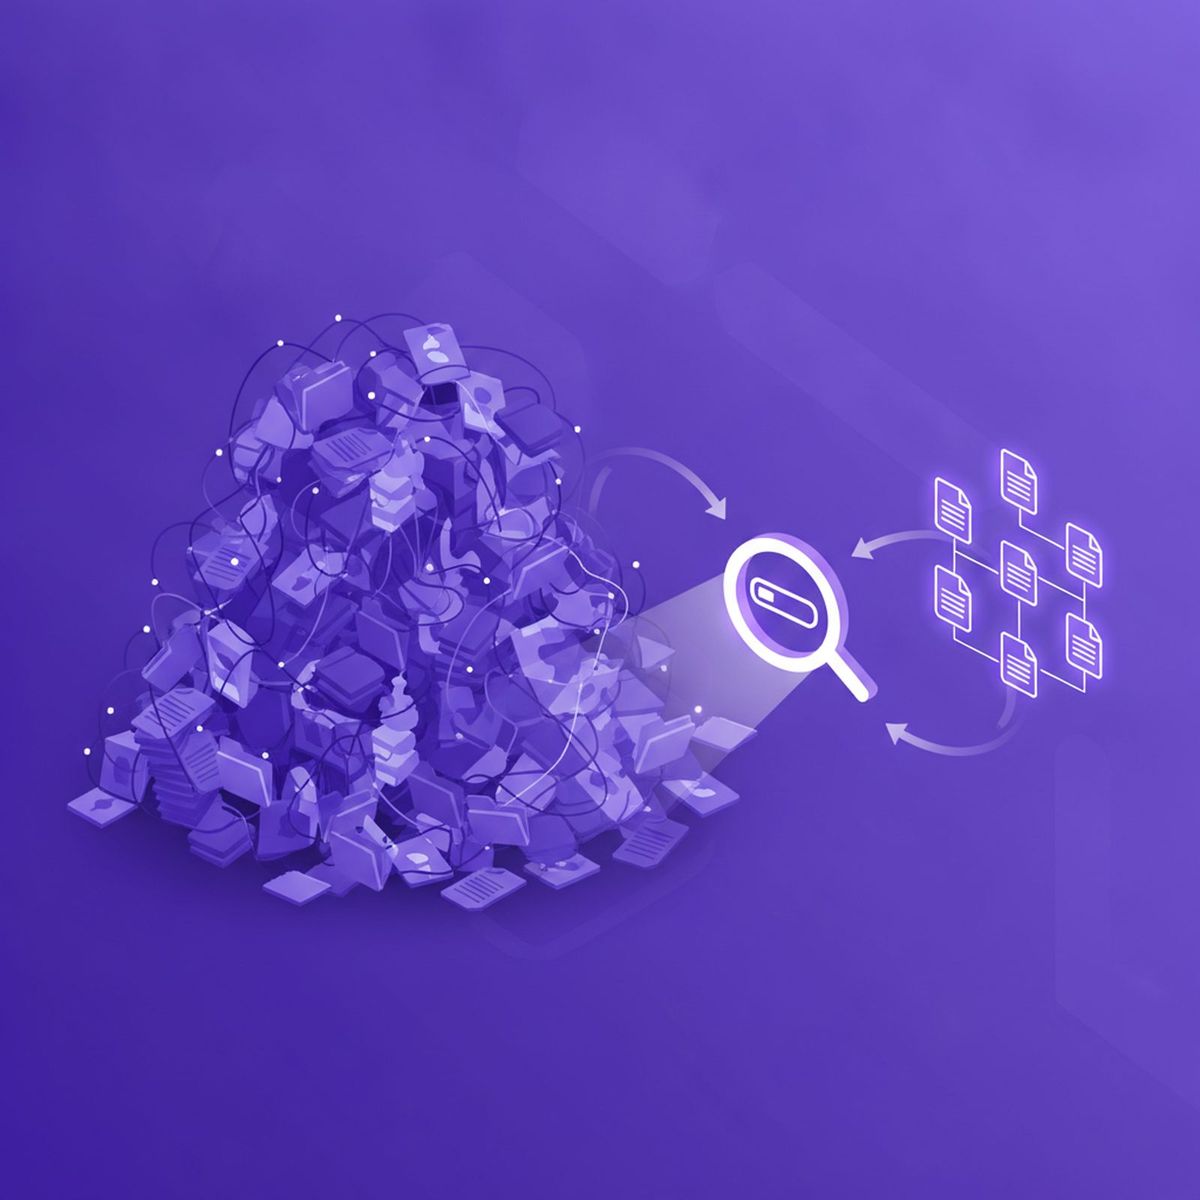
Every research or engineering organization eventually accumulates a few thousand PDFs, Word files and spreadsheets that are effectively unusable. Storage isn't the problem, disk is cheap. The problem is that nobody knows what's in there.
Why keyword search isn't enough
Ordinary search looks for character matches. If a document says "pressure drop in the transmission line" and you search "pipe pressure reduction", you get nothing, even though that's exactly what you wanted. In technical archives where every author uses their own vocabulary, that gap is wide.
What semantic search changes
Here the text is turned into numeric vectors that represent meaning. Search is no longer literal matching but semantic proximity. The result is that natural-language questions work, and you surface documents that contain none of your query's exact words.
The critical part: an answer without a citation is worthless
If a system answers your question but doesn't say which document and which page, it has given you nothing, you can't cite it and you can't verify it. In technical and legal use, an uncited answer is worse than no answer, because it might be wrong and nobody will notice. Judge any system by this: does every sentence of the answer link to a specific document and page?
Practical notes for a rollout
- Take scanned images seriously. A large share of older archives are scanned PDFs and stay invisible without OCR.
- Define access on day one. If everyone can see everything, the first confidential document that leaks ends the project.
- Make metadata mandatory, but minimal. Three required fields that always get filled beat fifteen optional ones that never do.
In short
The measure of a document management system isn't how many files it holds; it's how long a new engineer takes to find a sourced answer to a technical question. If that's more than a few minutes, you have an archive, not a knowledge base.
Once search works, the next step is answers you can check; see AI answers with citations, not guesses.
Recorded calls and meetings can join a searchable archive only once they are transcribed, and the transcript is only as good as the speech model. See what NVIDIA's Saudi dialect results mean for transcripts.
Frequently asked questions
Why doesn't keyword search work well on technical document archives?
Keyword search only matches characters, so it misses documents written in different words. A file about pressure drop in the transmission line will not show up for a search on pipe pressure reduction. In technical archives every author uses their own vocabulary, so that gap between what you type and what the document says is wide.
How is semantic search different from ordinary search?
Semantic search turns text into numeric vectors that represent meaning, then ranks documents by how close their meaning is to your question. Natural-language questions work, and you can surface documents that contain none of the exact words in your query. It is matching by meaning, not by spelling.
What should a document search system be judged on?
Judge it by whether every sentence of an answer links to a specific document and page. An answer without a citation cannot be verified or cited, and in technical or legal work it is worse than no answer, because it may be wrong and nobody notices. Also check how fast a new engineer finds a sourced answer.