"Where does the model run" is a governance question, not a technical one
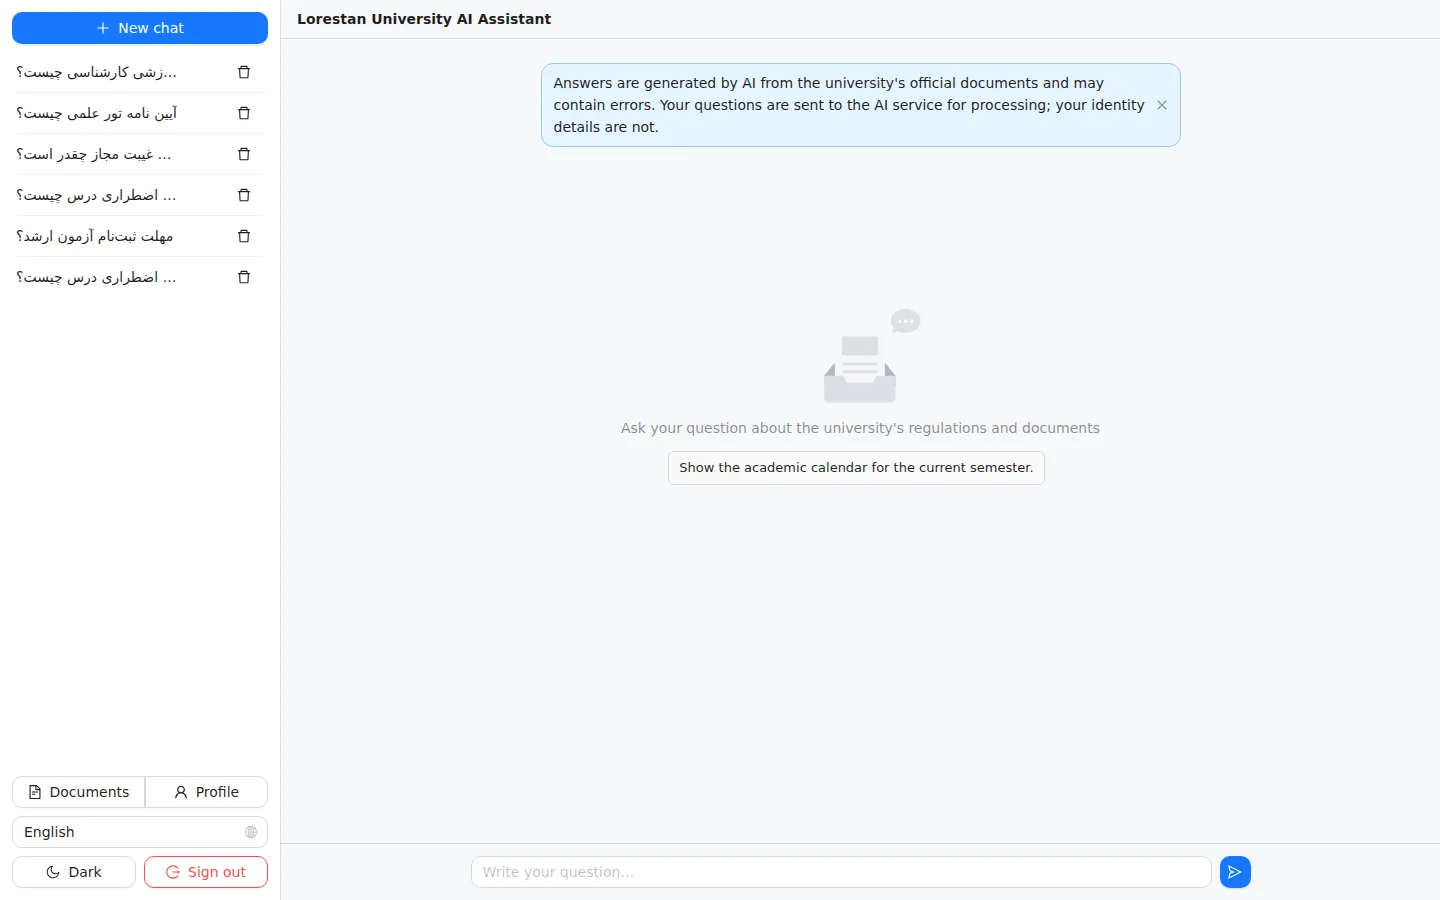
For most SaaS AI tools, deployment location is an implementation detail nobody outside engineering thinks about. For an assistant reading an organization's internal documents, it's the first question a legal or security team asks — and the honest answer is that it depends on what's in those documents, not on which option is technically simpler. FanMind supports both on-premise and cloud deployment for exactly this reason: the same product, a genuinely different answer depending on the data.
When on-premise is the only real answer
Personnel files, unpublished research, government correspondence, anything under a data-residency requirement — sending that to a third-party API, even a reputable one, is a governance decision someone has to sign off on and defend later. On-premise means the documents and the model inference both stay inside infrastructure the organization already controls and audits.
When cloud is the pragmatic choice
Public-facing content — course catalogs, published research, general institutional information — doesn't carry that risk, and cloud deployment means faster iteration, no GPU procurement, and no one on staff babysitting a model server. Forcing every deployment to be on-premise "to be safe" just moves the friction from a governance conversation to an infrastructure one, without actually reducing risk for content that was never sensitive.
The mistake both extremes make
Treating "on-premise vs. cloud" as a single yes/no decision for an entire organization, rather than a question answered per document set, either overspends on infrastructure the low-risk content didn't need or takes on liability the sensitive content couldn't afford. The right default is a platform that supports both and lets that decision follow the data, not a religious commitment to one deployment model before anyone's looked at what's actually being indexed.